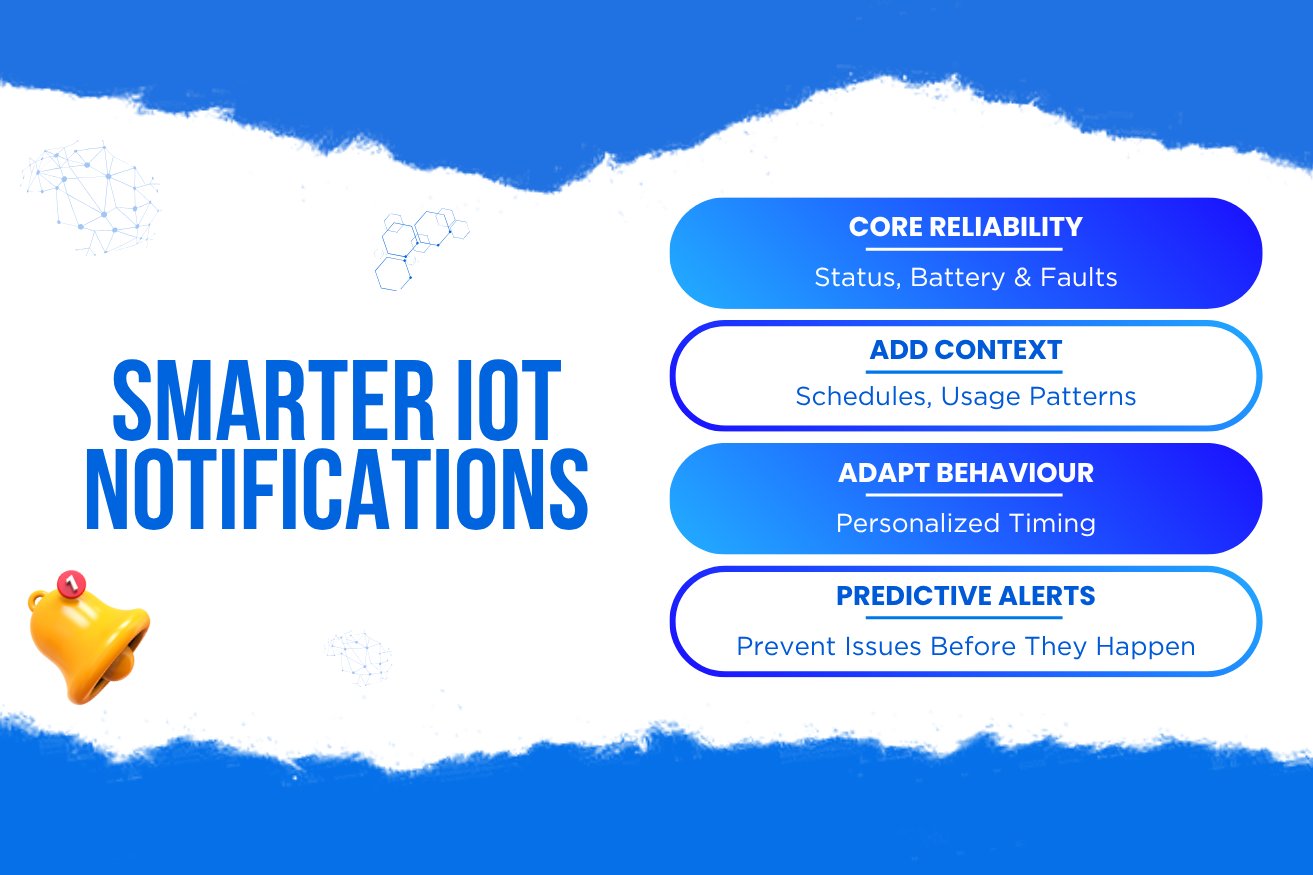
Every IoT system eventually has to tell somebody something. That turns out to be harder than detecting the condition in the first place, because the limiting resource is not sensing or bandwidth — it is human attention.
A notification system that sends too much gets muted within weeks. One that sends too little misses the event it existed to catch. Most deployments fail in the first direction, and they fail quietly: the alerts keep arriving, nobody reads them, and the monitoring system becomes decorative while still appearing healthy.
This guide covers how to design IoT notifications people keep acting on — severity, routing, escalation, suppression, and the metric that tells you whether any of it is working.
Every Notification Must Imply an Action
The single most useful filter in notification design is to ask, for each alert type: what should the recipient do within the next hour because of this?
If the honest answer is “nothing immediately”, it is not a notification. It belongs in a report, a dashboard, or a weekly digest. Alerts that carry no action train people to ignore the channel, which then also degrades the alerts that matter.
An ignored alerting system is worse than no alerting system, because everyone believes they are covered.
This is also why alert precision — the share of alerts that turn out to be real and worth acting on — matters more than recall in most deployments. Two false alarms do more damage to adoption than one missed event, because they change how every future alert is treated.
Severity Levels That Mean Something
Severity is useless unless each level maps to a different response and a different channel. Three or four levels are plenty; more than that and nobody remembers the difference.
| Level | Meaning | Channel | Response time |
|---|---|---|---|
| Critical | Safety, damage, or production stopped | Phone call or SMS, escalating | Immediate, 24/7 |
| High | Action needed today to avoid a problem | Push notification or SMS | Within working hours |
| Medium | Should be scheduled this week | Email or work order | Days |
| Info | Useful context, no action | Dashboard or digest | None |
A practical test for whether the levels are honest: if everything is critical, nothing is. When a system’s alerts cluster at the top severity, that is usually a design failure rather than an unusually dangerous process.
The Techniques That Prevent Alert Storms
Hysteresis and dwell time
A value oscillating around a threshold will generate endless alerts. Require the condition to persist for a defined period before alerting, and use a different, lower threshold for clearing than for raising.
These two mechanisms alone eliminate a large share of nuisance alerts in most systems.
Deduplication and grouping
One root cause often produces many alerts — a failed gateway makes fifty sensors look offline. Group related alerts into a single incident identifying the likely cause, rather than notifying fifty times.
Alarm lifecycle, not isolated messages
An alarm is a condition with a state: raised, acknowledged, cleared. Without explicit clear events, nobody can tell which problems are still active, and operators lose confidence in the list entirely.
Maintenance and suppression windows
Planned work generates conditions that look like faults. Suppressing alerts for specific assets during a window prevents the team from being trained to ignore real ones.
Rate limiting per recipient
Cap how many notifications one person can receive in an hour, with overflow summarised. Beyond roughly a handful per hour, additional alerts are not read.
Escalation with ownership
If a critical alert is not acknowledged within a defined time, it must reach someone else. Escalation paths are what convert a notification into a guarantee that somebody saw it.
What a Good Notification Contains
An alert that requires the recipient to open three systems to understand it will be dealt with slowly or not at all. The message itself should carry enough to decide.
- Which asset, named the way the operator knows it — not a device UUID
- What happened, in plain language, with the measured value and the threshold
- When it occurred, using event time rather than delivery time
- Why it matters, briefly — the consequence of ignoring it
- What to do next, or a link straight to the relevant procedure or work order
- Confidence, where the alert comes from a model rather than a fixed rule
Delivery latency matters too. If a device buffers readings for an hour, an alert derived from them is an hour old at best — which is why event time and ingest time should both be recorded, as covered in IoT event types.
Keeping a Notification System Healthy
Frequently Asked Questions
Conclusion
IoT notification design is attention engineering. Detecting a condition is a technical problem with a technical solution; getting a busy person to act on it reliably, for years, is a different discipline.
Make every alert imply an action, keep severity levels few and meaningful, suppress the noise with hysteresis and grouping, give alarms a lifecycle, escalate when nobody responds, and measure alerts per person and the action rate. A system that sends five trusted alerts a week delivers far more value than one that sends five hundred nobody reads.