A model that runs comfortably on a workstation will not fit on a microcontroller, and the gap is not small — it is often three orders of magnitude in memory and compute. Edge AI optimisation is the set of techniques that close that gap, ideally without losing the accuracy that made the model worth deploying.
Most of the available guidance treats these techniques as interchangeable tricks. They are not. Each targets a different bottleneck, and applying the wrong one wastes effort while the real constraint stays untouched.
This guide covers the main techniques, what each actually reduces, how much accuracy it typically costs, and the order to apply them in.
Identify the Bottleneck Before Optimising
There are four distinct limits, and they call for different responses.
| Constraint | Symptom | What helps |
|---|---|---|
| Flash / model size | The model will not fit in storage | Quantisation, pruning, smaller architecture |
| RAM / peak activations | Crashes or fails to allocate at runtime | Lower input resolution, restructure layers |
| Latency | Inference too slow for the deadline | Lower resolution, operator support, hardware acceleration |
| Energy | Battery life below target | Run inference less often; cascade cheap triggers |
The most commonly misdiagnosed one is RAM. Teams shrink the model file repeatedly while the actual limit is peak activation memory at the widest layer, which quantisation barely touches and input resolution changes dramatically.
Measure which of the four is binding before optimising. Three of the four techniques will do nothing for the constraint you actually have.
The Core Optimisation Techniques
Quantisation
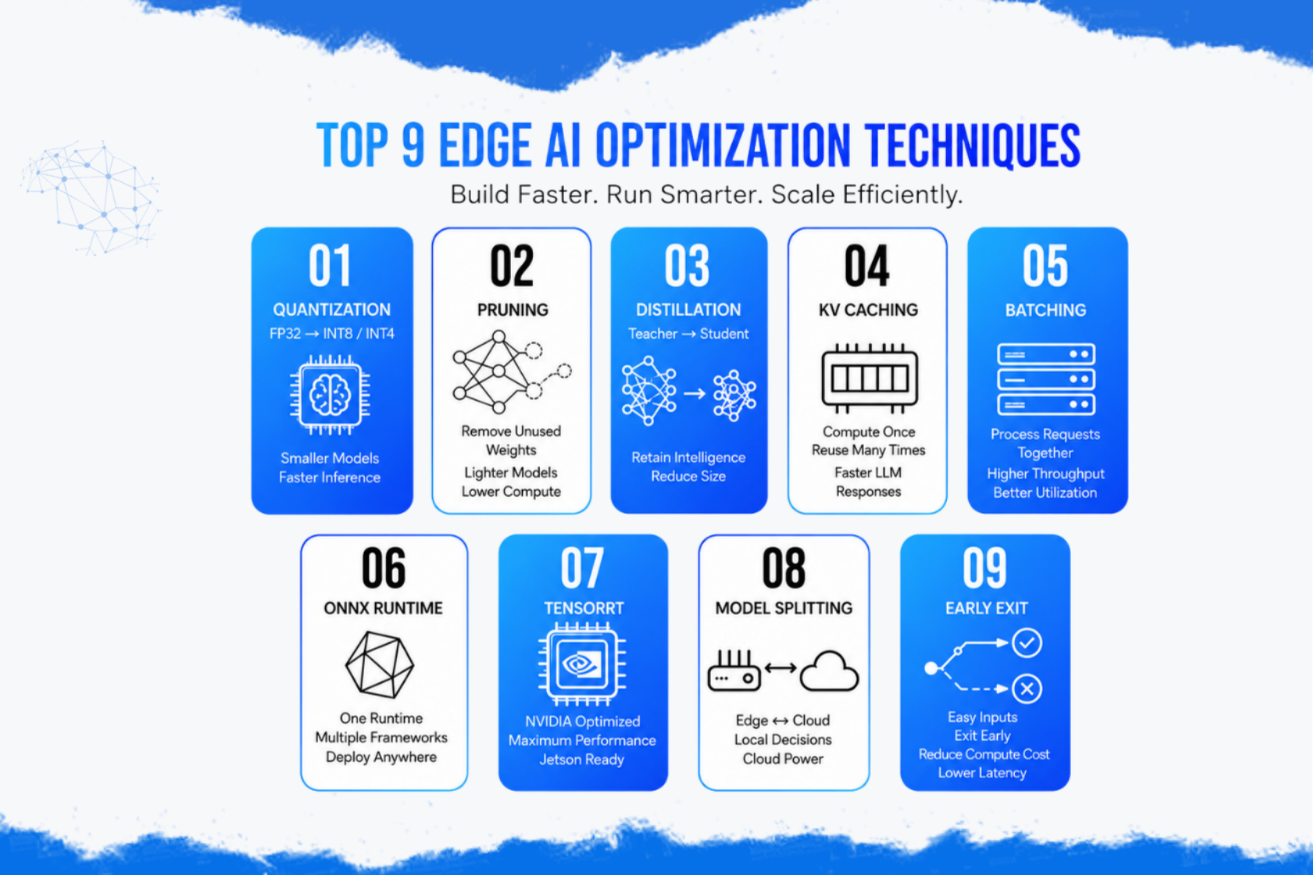
Representing weights and activations in lower precision — typically 8-bit integers instead of 32-bit floats. This reduces model size roughly fourfold and speeds up inference substantially, because most embedded processors handle integer arithmetic far more efficiently than floating point.
- Post-training quantisation — convert an existing trained model using a representative calibration dataset. Fast, and usually costs little accuracy.
- Quantisation-aware training — simulate the reduced precision during training so the model adapts. More work, better accuracy, and the right choice when post-training conversion loses too much.
This is almost always the first technique to apply, and frequently the only one needed.
Pruning
Removing weights or whole channels that contribute little to the output. Networks are typically over-parameterised, so a meaningful fraction can often be removed with minimal accuracy loss.
The important distinction is between unstructured pruning, which zeroes individual weights and only helps if the runtime supports sparsity, and structured pruning, which removes entire channels or filters and reliably reduces both size and latency on ordinary hardware. For embedded targets, structured pruning is usually the one that delivers.
Knowledge distillation
Training a small model to reproduce the behaviour of a larger one, learning from its outputs rather than only from labels. The small model often reaches accuracy it could not achieve trained directly on the data.
This is the technique to reach for when a compact architecture underperforms and you still have the larger model available to teach it.
Architecture choice
Often more effective than compressing a model designed for servers. Architectures built for constrained devices — using depthwise separable convolutions and similar efficiency patterns — are far better starting points than heavily pruned large networks.
If a model is being compressed by an order of magnitude, the architecture was probably wrong for the target.
Input reduction
The most underrated lever. Halving input resolution cuts compute roughly fourfold and reduces peak activation memory sharply, usually for far less accuracy loss than teams expect — because much of the discarded detail was never informative for the task.
Always test whether the task actually needs full resolution before optimising the model that consumes it.
Operator alignment and hardware acceleration
Accelerators support a defined operator set. A single unsupported layer forces a fallback to the CPU and can erase the entire speed advantage. Designing the network against the accelerator’s supported operators is often worth more than any compression.
A Sensible Optimisation Sequence
Frequently Asked Questions
Conclusion
Edge AI optimisation works best as a diagnosis followed by a targeted response, not as a sequence of tricks applied hopefully. Find whether flash, RAM, latency or energy is binding, then apply the technique that addresses it.
For most projects the order is: pick an architecture meant for constrained hardware, reduce the input, quantise to int8 with honest calibration, prune structurally if still needed, and profile on the real target at temperature. Done in that order, a model that seemed impossible usually fits with accuracy nobody misses.