Logo home 9

Over 10 years we helping companies reach their financial and branding goals. Onum is a values-driven SEO agency dedicated.

CONTACTS
Embedded IoT Solutions

Federated Learning in AIoT: When It Fits and When It Does Not

Category
Embedded IoT Solutions
Read Time
6 min read
Published
June 24, 2026
Status
Published

Federated learning trains across devices without collecting raw data. It solves a specific problem well and introduces several new ones.

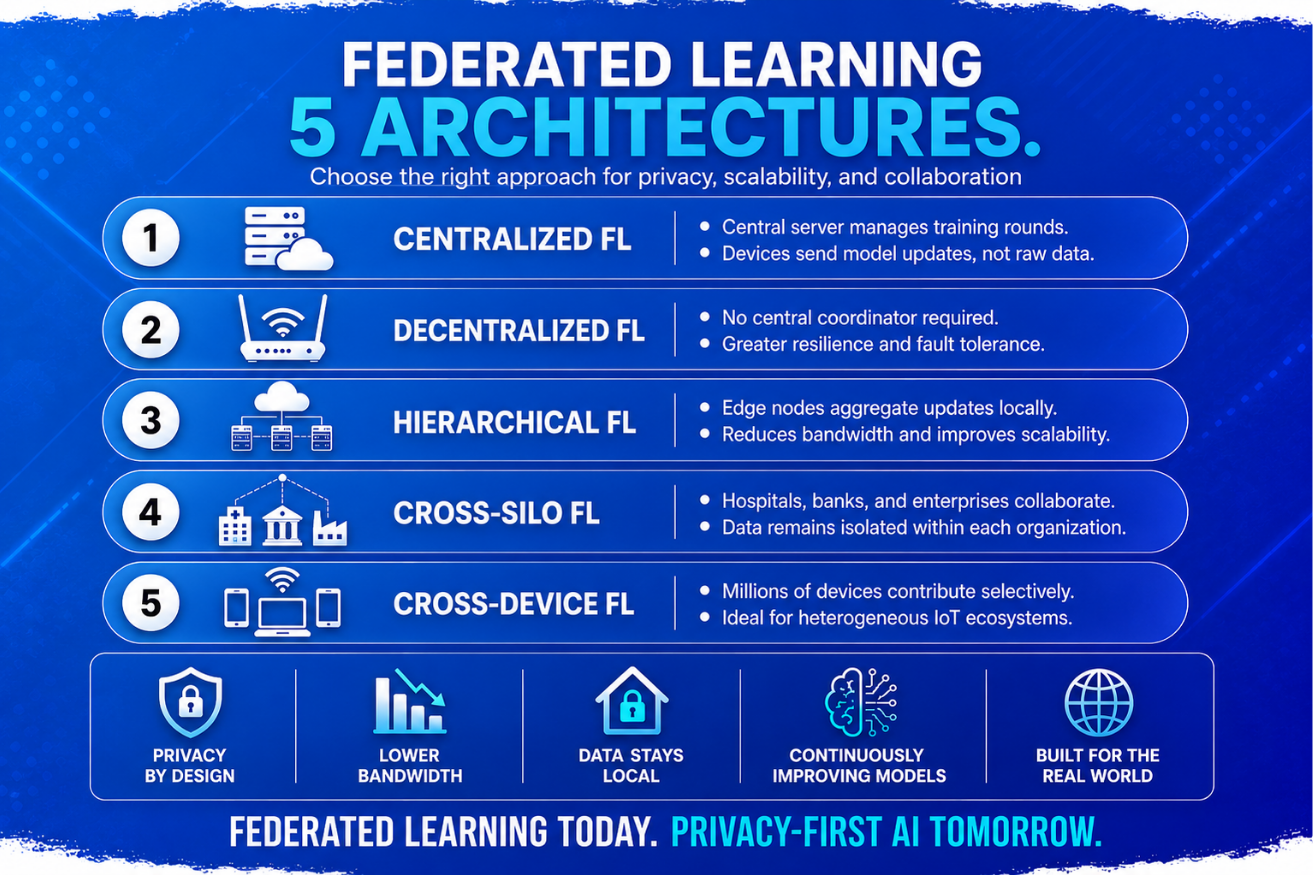
Federated learning trains a shared model across many devices without collecting their raw data. Each device trains locally on what it observes, sends only the resulting model updates, and a server combines those into an improved model that is sent back.

The appeal for connected products is obvious: better models from real deployment data, without the bandwidth cost or privacy exposure of centralising it. The reality is that federated learning solves a specific problem well and introduces several new ones, and most teams who consider it do not actually need it.

This guide explains how it works, when it genuinely fits, what it costs, and the simpler alternatives worth ruling out first.

Mechanics

How Federated Learning Works

1

Distribute the current model

The server sends the current global model to a selected subset of devices — typically those that are idle, charging or well connected, since training is expensive.

2

Train locally on local data

Each device performs a limited amount of training on data it already holds. The data never leaves the device, which is the entire point.

3

Return only the updates

Devices send back weight changes rather than observations. These are much smaller than raw data and far less directly revealing, though not automatically anonymous.

4

Aggregate into a new global model

The server averages the contributions, weighting by how much data each device used, then distributes the improved model. The cycle repeats.

The result is a model that has learned from the whole fleet’s experience while the fleet’s raw data stayed where it was generated.

Fit

When Federated Learning Is Genuinely the Right Answer

It is a strong fit when several of these hold at once:

  • Raw data cannot leave the device for regulatory, contractual, or privacy reasons — medical, workplace, or in-home sensing.
  • Transmitting the data would be impractical because it is high-rate audio, vibration or video on a metered link.
  • Local conditions differ meaningfully, so a model trained centrally on one site generalises poorly.
  • Labels exist naturally on-device through user behaviour or outcomes, without needing a human annotator.
  • Devices have real compute and power, since training is far heavier than inference.

That last condition rules out most microcontroller-class products immediately. Federated learning is realistic on gateways, vehicles, phones, and capable edge nodes — rarely on a sensor running from a coin cell.

Costs

What It Actually Costs You

Training on device is expensive
Backpropagation needs far more memory and energy than inference. Devices must be chosen for it, and training scheduled when power and thermal headroom allow.
Non-uniform data breaks naive averaging
Devices see very different distributions, which is exactly why federation is attractive and also why simple averaging can converge poorly or oscillate. This is the main practical difficulty.
Debugging is genuinely hard
When the global model degrades, the cause sits in data you cannot inspect. Diagnosis relies on aggregate statistics rather than examining examples.
Updates are not automatically private
Model updates can leak information about training data. Where privacy is the justification, differential privacy or secure aggregation is required — adding complexity and usually costing accuracy.
A poisoning surface exists
A compromised device can submit malicious updates. Robust aggregation and per-device identity become part of the threat model.
Substantial infrastructure
Orchestration, device selection, version management, and aggregation monitoring are a platform in their own right.
Alternatives

Simpler Options to Rule Out First

Most teams considering federated learning have a data access problem that a lighter approach solves.

If the problem is…Consider first
Too much data to transmitSend extracted features or only low-confidence cases
Privacy of raw mediaProcess on-device and transmit only derived results
Each site behaves differentlyPer-site fine-tuning of a centrally trained model
Limited labelled dataAnomaly detection trained on normal behaviour only
Occasional retraining neededCollect from a consented subset of devices

Federated learning is the right answer when raw data genuinely cannot move. If it can move for even a small sample of devices, a simpler pipeline usually wins.

Practice

Deploying Federated Learning Successfully

1Confirm the constraint is real
Write down why raw data cannot leave. If the answer is bandwidth rather than law or contract, feature extraction is likely cheaper and simpler.
2Size devices for training, not inference
Memory and energy requirements are an order of magnitude higher. This usually means gateways or mains-powered nodes rather than sensors.
3Select participants deliberately
Train only on devices that are charging, idle and well connected, and rotate so the global model is not shaped by one unrepresentative subset.
4Plan for uneven data from the start
Choose aggregation that tolerates heterogeneous distributions, and monitor convergence rather than assuming averaging behaves.
5Add privacy mechanisms if privacy is the reason
Raw updates are not inherently private. If the justification is privacy, implement it explicitly and accept the accuracy cost.
6Keep a validation set you control
You cannot inspect training data, so an independent held-out set is the only way to verify each global model before release — part of the wider edge AI deployment discipline.
FAQ

Frequently Asked Questions

What is federated learning in AIoT?
A method of training a shared model across many devices without collecting their raw data. Each device trains locally and returns only model updates, which a server aggregates into an improved global model that is distributed back to the fleet.
When should you use federated learning?
When raw data genuinely cannot leave the device for legal, contractual or privacy reasons, when transmitting it is impractical, when local conditions differ enough that a central model generalises poorly, and when devices have the compute and power to train rather than only infer.
Is federated learning private by default?
No. Model updates can leak information about the data they were trained on. If privacy is the justification for the architecture, differential privacy or secure aggregation must be added explicitly, which adds complexity and usually costs some accuracy.
Can microcontrollers do federated learning?
Generally no. Training requires far more memory and energy than inference, so federated learning is realistic on gateways, vehicles, phones and capable edge nodes rather than on sensors running from small batteries.
What are the alternatives to federated learning?
Sending extracted features instead of raw data, uploading only low-confidence cases, processing media on-device and transmitting results only, fine-tuning a central model per site, or collecting full data from a small consented subset of devices.
Wrapping Up

Conclusion

Federated learning is a genuinely useful technique for a narrow situation: raw data that cannot move, devices capable of training, and conditions varied enough that a central model underperforms.

Outside that situation it adds orchestration, debugging difficulty, convergence problems with uneven data, and a privacy story that only holds if implemented deliberately. Check whether feature extraction, selective upload, or per-site fine-tuning solves the problem first — and if the constraint is real, size the devices for training and keep an independent validation set you control.

About MetaDesk Global

Engineering the Next Generation of Connected Products

MetaDesk Global helps startups and enterprises develop intelligent connected products that combine embedded systems, Industrial IoT, Edge AI, and cloud technologies. Our expertise includes:

Industrial IoT (IIoT) Solutions Embedded Firmware Development Edge AI Development Predictive Maintenance Systems PCB Design IoT Gateway Development Cloud Integration OTA Firmware Updates AIoT Product Development End-to-End Product Engineering

From hardware design to AI-powered industrial platforms, we build scalable solutions for the next generation of connected products.

Start Your Project

Building a Connected Product?

We design IIoT sensor networks, Edge AI pipelines, and secure cloud platforms — from prototype to production.

Request a Free Quote →