Edge AI is frequently presented as a straightforward upgrade: move the model onto the device and gain speed, privacy, and independence from the cloud. In practice every one of those gains is bought with something, and the currency is usually accuracy, power, or unit cost.
There is no configuration that is fast, accurate, cheap, and low-power simultaneously. Designing an edge AI system means deciding which of those you are willing to give up, deliberately, with the consequences understood.
This guide sets out the six trade-offs that define every edge AI deployment, how each one behaves in practice, and how to decide where to sit on each axis before the hardware is fixed.
What Edge AI Actually Changes
Edge AI means running inference on or near the device that captured the data, rather than sending the data somewhere else to be interpreted. The shift sounds architectural but its consequences are mostly economic.
- Latency collapses from a network round trip to a local computation
- Bandwidth drops sharply, because conclusions are far smaller than the signals behind them
- Availability stops depending on connectivity
- Privacy improves structurally, since raw data need never leave the device
- Compute becomes fixed and small, rather than elastic and large
That last point is the source of every trade-off that follows. In the cloud, more compute is a billing decision. On a device it is a hardware decision, made once, before deployment, for the life of the product.
Edge AI does not remove constraints. It converts variable cost into fixed capability, and everything else follows from that.
The Six Edge AI Trade-Offs
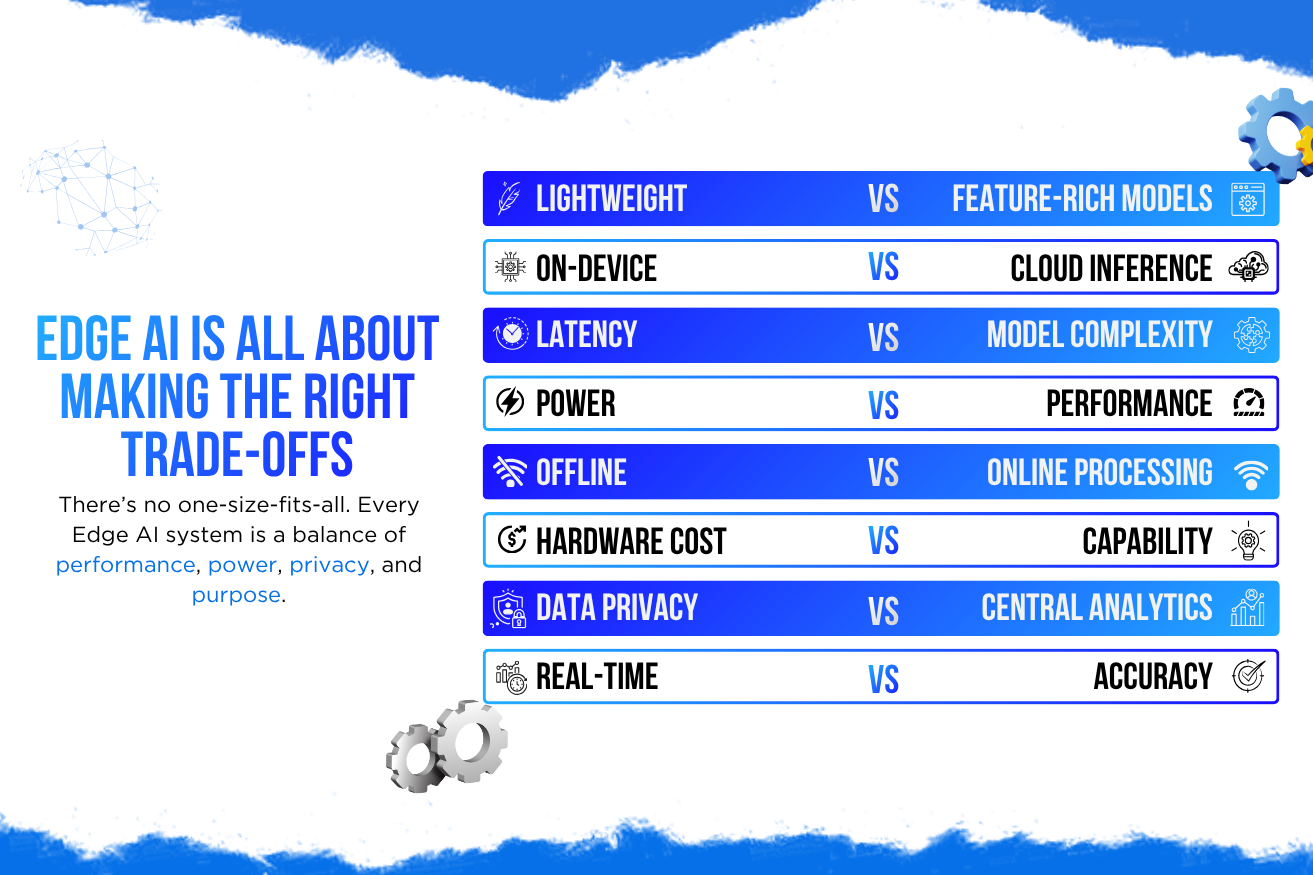
Lightweight models vs feature-rich models
Smaller models fit in memory, run fast, and consume little energy. Larger models capture more subtle patterns and handle more edge cases.
Establish the minimum accuracy that makes the product useful, not the maximum achievable. Many deployments discover that a compact model at 93 percent accuracy delivers essentially the same business outcome as a large one at 96 percent, at a fraction of the cost — because the operational process absorbs occasional errors anyway.
Where the gap genuinely matters, the answer is often a two-stage design: a small model runs continuously and a larger one is invoked only on ambiguous cases.
On-device inference vs cloud inference
This is rarely all-or-nothing, and treating it as a binary choice is the most common architectural mistake in edge AI.
- Device — detection, filtering, and anything needing an immediate response
- Gateway or edge node — correlation across several devices in one location
- Cloud — training, retraining, fleet-wide analysis, and long-horizon patterns
The device decides what happened. The cloud decides what it means across the fleet, and improves the model the device runs.
Latency vs model complexity
Inference time scales with model size, but inference is often not the dominant term. Sensor readout, pre-processing, and post-processing frequently consume more of the budget than the model itself.
The practical implication is that reducing input resolution or sampling rate usually buys more latency headroom than switching to a lighter architecture — and costs less accuracy than teams expect, because much of the discarded information was never informative.
Power consumption vs performance
On battery-powered devices this trade-off dominates all others. The useful ordering is consistent: transmitting costs far more energy than computing, and computing costs far more than sensing.
That ordering is precisely why edge AI extends battery life rather than shortening it. Running a small model to avoid transmitting a continuous stream is usually a large net saving. The failure mode is running a model continuously when a cheap trigger — a threshold, a motion detector — could have gated it. Cascade your compute: cheap detection wakes expensive inference.
Offline reliability vs cloud connectivity
A device that can infer locally keeps working when the network fails. But a fully autonomous device is also harder to correct: you cannot adjust its behaviour without an update, and you may not see what it is deciding.
The balance most systems settle on is local autonomy for decisions, cloud oversight for visibility. The device acts alone; it reports what it decided, and the platform monitors whether those decisions still look right — which requires the offline-first behaviour of buffering and replaying that record rather than discarding it during an outage.
Hardware cost vs AI capability
Every increment of on-device capability appears in the bill of materials for every unit ever produced. At volume, a few dollars per device is a substantial commitment.
The asymmetry worth remembering: under-specifying is far more expensive than over-specifying. Insufficient headroom means a hardware revision to add any future capability, while modest surplus costs a small amount per unit and preserves every option. Choose the part that supports the model you expect in two years, not only the one you have today.
How the Application Decides the Balance
The right position on each axis follows from what the product does. Four common profiles cover most cases.
| Profile | Dominant constraint | Typical resolution |
|---|---|---|
| Battery sensor, years of life | Power | Tiny model, cascaded triggers, rare transmission, accept lower accuracy |
| Safety or control loop | Latency and determinism | Local inference only, bounded execution time, no cloud in the decision path |
| Industrial inspection | Accuracy | Higher-capability hardware, mains power, larger model, edge node not device |
| Consumer product at volume | Unit cost | Smallest part that meets the requirement, with deliberate headroom for updates |
Notice that no profile optimises everything. Each accepts a weakness explicitly, which is exactly what makes it a design rather than a compromise discovered later.
Making the Decisions in the Right Order
The deeper set of implementation problems that surface after these decisions — fleet variation, drift, and monitoring — are covered in our guide to edge AI deployment challenges. For the specific question of which silicon class to target, see our comparison of edge AI hardware options.
Frequently Asked Questions
Conclusion
Edge AI is not a free upgrade, and teams that treat it as one usually discover the bill in the form of a battery that lasts months instead of years, or a hardware revision that was avoidable.
Approach it as a set of explicit choices instead. Fix the latency deadline from the process, state the accuracy you actually need, benchmark on real hardware under real thermal conditions, cascade compute so expensive models run rarely, and leave enough headroom to improve after launch. Systems designed that way tend to be modest on paper and remarkably durable in the field.